Healthcare
Production-ready document processing to transform patient care
Trusted by leading AI teams
Deploy Document Processing in Mission-Critical Flows
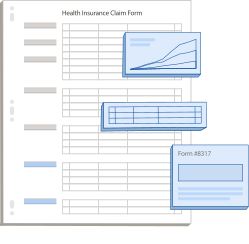
Parse Dense Layouts
CMS-1500s pack dozens of fields into tight grids. Our OCR + VLM pipeline detects every element type regardless of alignment shifts or form variations.
( fig.01 )
Handle Hundreds of Rows
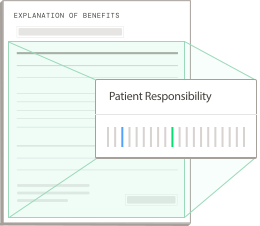
EOBs contain nested tables, spanning cells, and inconsistent formatting across payers. Multiple array extraction strategies return clean output with precise bounding boxes for every value.
( fig.02 )
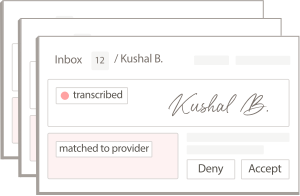
Decode Messy Handwriting
Standard OCR chokes on physician handwriting. Our hybrid pipeline routes handwritten elements to purpose-built VLMs trained to interpret real-world medical scrawl.
( fig.03 )
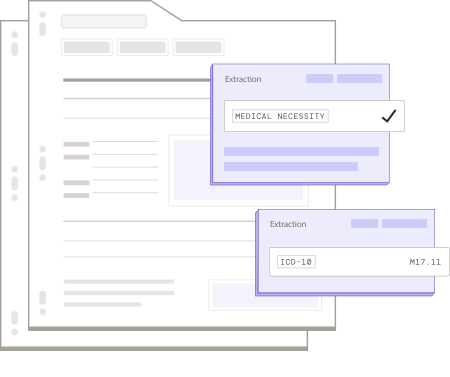
Detect Checkboxes Reliably
Prior auth forms are filled with checkboxes, X-marks, and partial fills. Get accurate field detection with confidence scores on every extraction and automatic flagging when human review is needed.
( fig.04 )
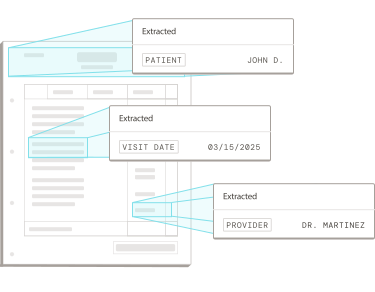
Scale to 1,000+ Page Files
Patient charts span years of visits, labs, and notes. Smart chunking and merging strategies ensure accurate extraction across the entire record without token limits or context cutoffs.
( fig.05 )
See healthcare documents parsed side by side
Side-by-side layout detection and markdown parsing across providers on real clinical and claims documents.
Lab Report
Diagnostic panel results with reference ranges and flags.
Frequently asked questions
Any document your healthcare pipeline receives, extracted accurately at a per-page cost that holds up at production volume, with no templates to maintain. That includes CMS-1500 claim forms, explanations of benefits (EOBs), prior authorization forms, referrals, and patient charts, across every form variation and payer format. Teams like SamaCare, Flatiron Health, and Amgen use Extend for this.
A hybrid pipeline routes handwritten elements to purpose-built VLMs trained to interpret real-world medical handwriting, while printed fields go through OCR.
Yes. Smart chunking and merging strategies extract across the entire record, so charts spanning years of visits, labs, and notes never hit token limits or context cutoffs. Flatiron Health replicated 6 months of work in 2 weeks with Extend and is scaling it across the 5 million people with cancer in its network. Read the Flatiron Health case study.
Multiple array extraction strategies handle nested tables, spanning cells, and inconsistent formatting across payers, returning clean output with bounding boxes for every value. On LongArray-Extract, a public benchmark of 45 financial, clinical, and legal PDFs with up to about 2,200 rows each, Extend scored 99.2% mean accuracy, completed every document, and finished 2.8x faster than the closest peer, ahead of every document-AI platform and frontier model tested. See the LongArray-Extract results.
Every extracted field returns a confidence score, and uncertain values, such as partial fills on prior auth checkboxes, are flagged automatically for human review. SamaCare built its prior authorization autofill on Extend in 3 weeks and now processes over 500,000 pages a month at 98% accuracy, including handwriting, signatures, and checkboxes. Read the SamaCare spotlight.